Drops Alternative for English Vocabulary: Picture Matching or Contextual Recall?
October 20, 2026
Images help when the unknown word has no hook. They are weak when the test lets the picture do the remembering for you. If you are looking for a Drops alternative for English vocabulary, that distinction is the whole decision: do you want better first contact with a word, or a system that later makes you produce the word from meaning and context? The first is onboarding. The second is learning.
Drops is the obvious visual-learning foil because it is image-led vocabulary practice. That is useful. A picture can attach an unfamiliar word to a mental scene faster than a bare definition can. The failure mode is treating that attachment as the full loop.
A Drops alternative for English vocabulary has to test recall, not recognition
Recognition is “I know it when I see it.” Recall is “I can produce it when the situation calls for it.” Vocabulary growth depends far more on the second.
Picture matching often keeps the word, the image, and the answer set on screen. That trains selection. The learner can succeed by noticing visual familiarity, eliminating options, or remembering layout. Those are not useless skills, but they are not the skill you need when writing a sentence, reading a novel, or hearing a word without a friendly illustration beside it.
WordLab uses images, but as introductions, not as the main test. Every word you have never seen gets a word-card introduction before the puzzle, so you are not quizzed cold on a word you could not possibly know. The first ~1,500 words have illustrated word cards styled like collectible game cards: an image designed to evoke the word’s meaning, a definition, an example sentence matching the image, and connotation tags.
After that introduction, review happens in the crossword. The image did its job; recall is then tested in context.
Images are good anchors and bad endpoints
Take envisage: “imagine or picture in your mind.” The card can make the meaning vivid. Its example sentence is: “She could easily envisage a future where robots handle all household chores.”
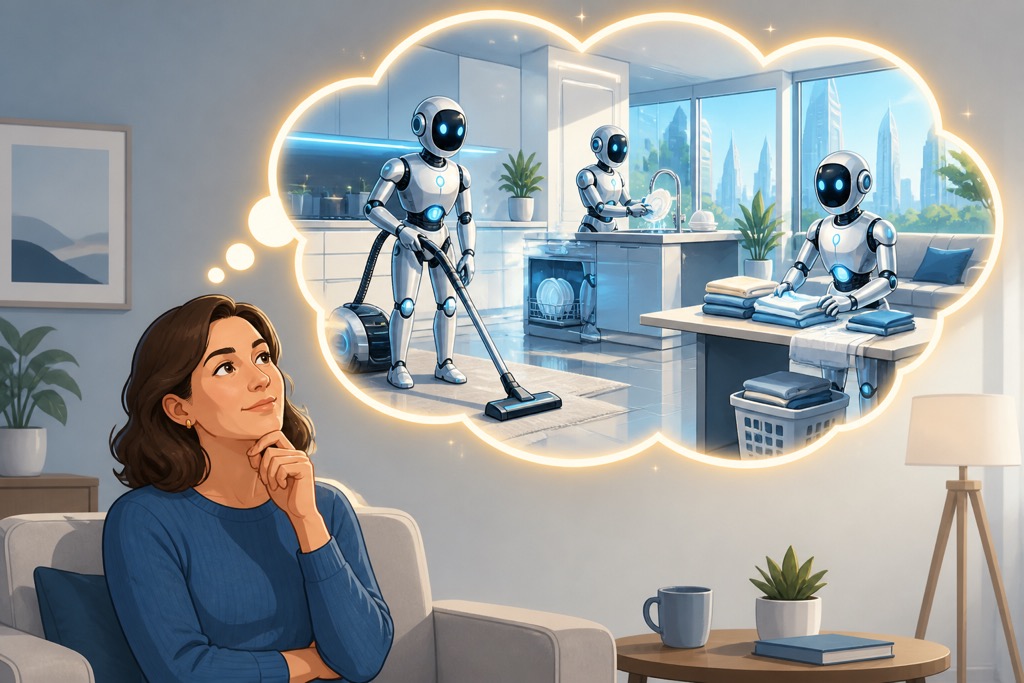
That image is doing real work. It gives the word a scene. It prevents the sterile glossary effect where a formal verb floats beside a paraphrase and never attaches to anything.
But the image cannot finish the job. Envisage is not a banana, a dog, or a train. It is a formal, thoughtful, forward-looking verb. You need to know the kind of sentence it belongs in, the tone it carries, and the clue pattern that should summon it. An image can suggest that. A fill-in-the-blank clue has to test it.
WordLab clues are fill-in-the-blank sentences plus a meaning-evoking hint. Recall happens in context, not against a definition. That matters because many English vocabulary words are not cleanly picturable. Recapitulate means “summarize briefly.” The card can stage a professor at the end of a lecture; the durable skill is producing recapitulate when a sentence calls for “briefly summarize.”
Context blocks the wrong shortcuts
A definition-only flashcard has its own overfitting problem: you memorize the phrasing on the back. A picture-only drill has a parallel problem: you memorize the image. In both cases, the surface can become the cue instead of the meaning.
WordLab avoids fixed-surface training by cycling every word through multiple differently phrased clues — currently 3 per word — under one spaced-repetition schedule per word. The schedule tracks the underlying word, not each clue as a separate item. Different clues, one memory target.
That design matters. If recapitulate only ever appears beside “summarize briefly,” you can learn a two-word translation pair. If it appears in a lecture sentence, a meeting sentence, and a written-summary sentence, the stable thing across reviews is the word’s function. There is no single phrasing to overfit to.
The clue pipeline exists for that reason. Clues are produced by an iterative Creator → Validator → Guesser → Reviser pipeline using frontier language models. A clue can undergo up to 7 revisions before acceptance, against quality criteria refined through repeated in-app revision rounds. The point is not cute crossword filler. The point is a context that permits the target word and rules out nearby wrong words.
For a deeper version of this recognition-versus-recall distinction, see why you can recognize a word but can’t find it when you need it.
Spaced review matters after the picture has done its job
First exposure is cheap. Maintenance is the expensive part.
A vocabulary app can show you beautiful words for a week and still leave you with nothing durable if it does not bring each word back at the right time. Spaced repetition means reviews are scheduled after increasing intervals when you succeed and shortened when you struggle. Retrieval practice — testing yourself instead of rereading — is one of the cleanest mechanisms in learning; Roediger and Karpicke’s test-enhanced learning work is a canonical result here: taking memory tests improved long-term retention.
WordLab delivers spaced repetition through dynamically generated crossword puzzles. Due words become puzzle answers.
The grading is automatic. WordLab infers fast, normal, or slow recall from solve timing, normalized for clue and word length. No Again/Hard/Good/Easy buttons. No self-grading decision fatigue. If you recall the word quickly from context, the schedule sees that. If you grind through it slowly, the schedule sees that too.
This is the part visual matching cannot replace. A picture can help you start. It cannot decide when envisage is about to decay from memory, generate a new contextual clue for it, and make you fill the answer in a crossword.
The decision rule: use pictures for entry, contextual recall for retention
If your main goal is broad language sampling, a visual app can be pleasant. If your main goal is English vocabulary growth, especially beyond concrete beginner nouns, the decisive question is narrower:
Can the app make you retrieve the word when the picture is gone?
WordLab’s answer is the crossword. The word card introduces the meaning. The puzzle then asks for the word in context. The spaced-repetition schedule decides when it comes back. Multiple clue phrasings prevent you from memorizing one prompt.
That is why this design targets a different problem from picture matching. You get retrieval practice inside dynamically generated crosswords, with automatic timing-based grading instead of Again/Hard/Good/Easy buttons.
More on that design here: a vocabulary app should train recall in context.
WordLab is not the right replacement for every Drops user
WordLab is English only and iOS only. Word cards/images currently cover the first ~1,500 words. WordLab also trains one sense per word so far, not full polysemy. If you need Android, multiple languages, or a picture-first tour of basic travel vocabulary, skip it.
If you want a Drops alternative for English vocabulary that still uses images but does not stop at image association, try WordLab on iPhone or iPad. It is free with no ads.